 Dodi Irawan
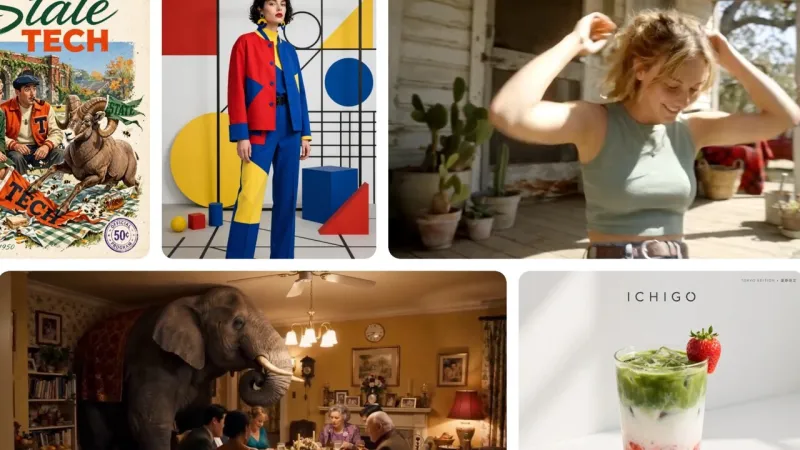
MENLO PARK, California – Meta has recently unveiled Muse, a sophisticated artificial intelligence model designed to generate images, but its reliance on publicly available Instagram photos for training data has immediately ignited a fierce debate among privacy advocates and users regarding data exploitation and ethical boundaries. The introduction of Muse represents Metas latest foray into generative AI, yet it arrives shadowed by significant criticisms concerning user consent and the broader implications for personal data.
Muse, as detailed by Meta, functions by converting text prompts into high-quality visual content, leveraging a vast repository of images. The models distinguishing feature, and simultaneously its point of contention, lies in its reported use of Instagram photographs for its developmental training datasets. This method aims to produce more realistic and contextually relevant images, drawing from the immense visual library accumulated on the popular photo-sharing platform.
Critics contend that while Instagram photos may be publicly accessible, their use for training a commercial AI model without explicit, granular consent constitutes a significant breach of user privacy expectations. Concerns revolve around the notion that personal photographs, intended for social sharing within a certain context, are now being repurposed for machine learning, potentially stripping users of control over their digital likenesses and creative output.
The debate extends beyond mere usage to questions of data ownership and the potential for misuse. Users are questioning whether their visual data, once uploaded, becomes fair game for corporate AI development, even if anonymized or aggregated. Fears include the possibility of deepfakes, unauthorized replication of styles, or the creation of imagery derived from personal photos in ways unintended by the original creators.
Meta has yet to issue a comprehensive public statement directly addressing the burgeoning privacy backlash against Muse. Historically, tech giants have cited terms of service agreements that grant broad licenses for user-generated content, but privacy advocates argue these agreements often do not explicitly cover the nuanced application of AI model training.
For the millions of Instagram users, the advent of Muse raises uncomfortable questions about the longevity and control of their digital footprint. It challenges the perceived boundary between public sharing and corporate data harvesting, prompting many to reassess their comfort level with social media platforms as repositories for their personal content.
This situation is not unique to Meta; other major AI developers have faced similar scrutiny over their data sourcing practices. However, Metas deep integration with consumer-facing platforms like Instagram intensifies the spotlight, given the intimate and personal nature of photo sharing compared to more general web crawling data collection. The conversation around ethical AI development is quickly moving towards requiring greater transparency in data acquisition.
“This development highlights a critical disconnect between user expectations of privacy and the expansive data needs of artificial intelligence,” stated Dr. Lena Hoffman, a digital ethics researcher at the University of California, Berkeley. “Companies must prioritize clear communication and robust consent mechanisms to maintain user trust, especially when leveraging highly personal data like photographs.”
The privacy concerns around Muse also underscore the limitations of current regulatory frameworks. While regions like the European Union have robust data protection laws such as GDPR, the specific nuances of AI model training using public social media data remain a grey area that regulators worldwide are only now beginning to grapple with. Lawmakers are urged to consider new legislation that specifically addresses generative AI and data consent.
The controversy surrounding Muse serves as a potent reminder of the ethical tightrope walking required in the rapid advancement of artificial intelligence. As AI capabilities expand, so too must the frameworks governing their development and deployment, particularly when personal data fuels their innovation. This instance spotlights the urgent need for a global dialogue on responsible AI.
Social media forums and tech communities are already abuzz with discussions, ranging from calls for users to delete old content to demands for opt-out mechanisms. This potential user backlash could force Meta to reconsider its approach or at least offer more transparent controls for data usage in AI training.
The growing awareness of data privacy in the digital age, as exemplified by the Muse debate, aligns with broader societal calls for greater control over digital interactions. A similar sentiment echoes in ongoing discussions, such as the initiative by Veneto Students Demanding Social Media Ban for Under-14s, signaling a collective desire for more ethical and user-centric digital environments.
Ultimately, the future of Meta's Muse AI and its integration with Instagram may hinge on the company's ability to navigate these complex ethical waters. Addressing the privacy criticisms proactively and transparently will be crucial for maintaining user trust and ensuring the sustainable development of its AI initiatives.